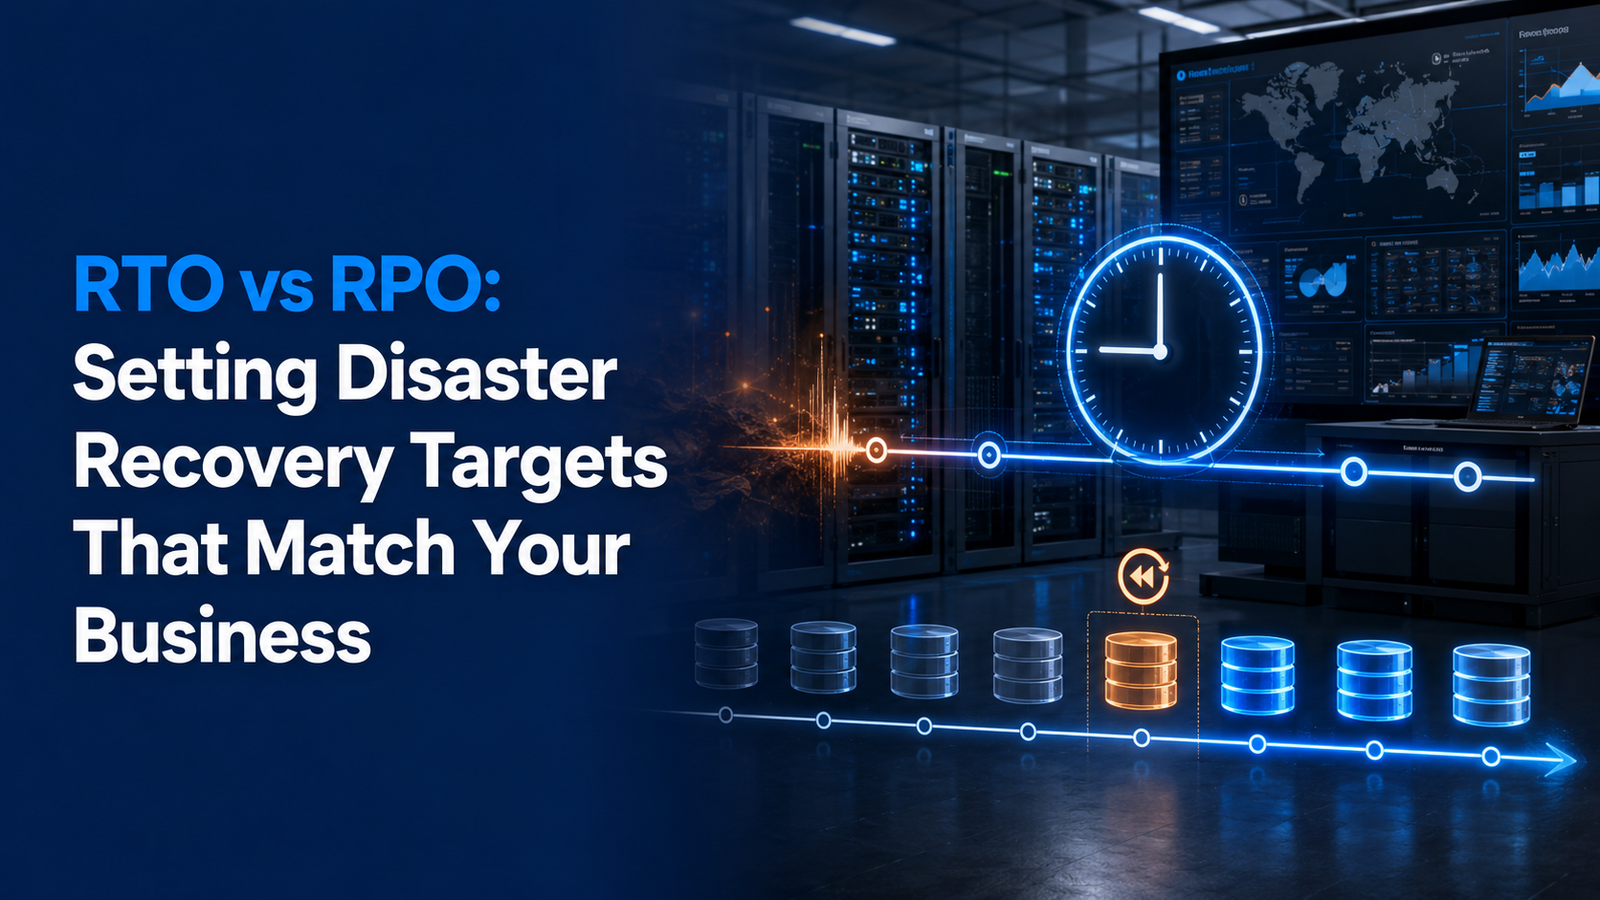
Every disaster recovery plan comes down to two numbers — how long you can be down, and how much data you can lose. Confuse them and you’ll either overspend on protection you don’t need, or discover the gap at the worst possible moment.
When something goes wrong — a ransomware hit, a failed data center, a botched deployment — two questions decide how bad it gets. How long until you’re running again? And how much of your data is gone for good? Those two questions have names: Recovery Time Objective (RTO) and Recovery Point Objective (RPO). They sound similar, they’re almost always quoted together, and they’re constantly confused — but they measure completely different things.
KEY TAKEAWAY
RTO is about time (how long you can be down); RPO is about data (how much you can afford to lose). Set them per workload, not once for everything — and remember that tighter targets always cost more, so the goal is to match each target to real business impact, not to minimize both.
What is RTO (Recovery Time Objective)?
RTO is the maximum acceptable length of time a system can be offline after an incident before the impact becomes unacceptable. It answers one question: how quickly must we be back?
If your e-commerce checkout has an RTO of one hour, your DR plan has to be able to restore it within an hour of an outage. RTO drives how fast — and therefore how expensive — your recovery mechanism needs to be. An RTO measured in seconds implies a hot standby environment with automated failover; an RTO of a day might be satisfied by restoring from a backup.
What is RPO (Recovery Point Objective)?
RPO is the maximum acceptable amount of data loss, measured as a length of time. It answers a different question: how much recent data can we afford to lose?
If your RPO is 15 minutes, your systems must be backed up or replicated at least every 15 minutes, so that in the worst case you lose no more than 15 minutes of data. RPO drives how frequently you back up or replicate. A near-zero RPO means continuous replication; an RPO of 24 hours means a nightly backup is enough.
The key difference, in one line
RTO looks forward from the moment of the incident — how long until we recover? RPO looks backward from that same moment — how far back is our last good copy? One is measured in downtime, the other in lost data. A system can have a tight RTO and a loose RPO, or the reverse — they’re set independently.
A simple way to hold the two apart: picture a car crash. RTO is how long until the car is repaired and back on the road. RPO is how far back you’d have to rewind to the last save point before the crash. Repair time versus lost ground.
RTO vs RPO at a glance
| Dimension | RTO | RPO |
|---|---|---|
| What it measures | Downtime — time to recover | Data loss — time between backups |
| Question it answers | How fast must we be back? | How much data can we lose? |
| What it drives | Failover & recovery speed | Backup / replication frequency |
| Tight target needs | Hot standby, automated failover | Continuous / frequent replication |
| Loose target allows | Restore from backup | Periodic (e.g. nightly) backups |
| Measured from incident | Forward (time to recover) | Backward (to last good copy) |
How to set targets that match your business
The most common — and most expensive — mistake is setting one RTO and one RPO for everything. Your archive of five-year-old invoices does not need the same protection as your checkout system. Instead, tier your workloads by business impact and set targets per tier:
Setting targets by workload tier
| Tier | Examples | Typical RTO / RPO |
|---|---|---|
| Mission-critical | Revenue systems, customer-facing apps, core databases | Minutes |
| Important | Internal apps, reporting, back-office systems | Hours |
| Non-critical | Archives, dev/test, rarely-used tools | A day or more |
For each workload, ask two business questions: what does an hour of downtime actually cost us, and what does losing an hour of this data cost us? The honest answers — in money and risk — set the targets. RTO and RPO are business decisions expressed in technical terms, not technical decisions made in isolation by IT.
The cost trade-off nobody mentions
Tighter targets cost more — often a lot more. A near-zero RPO means continuous replication and the infrastructure to support it. A near-zero RTO means a standby environment running, and billing, alongside production. Halving your RTO can more than double the cost of protecting that workload. That’s exactly why matching targets to business impact matters: you spend the protection budget where downtime and data loss genuinely hurt, and save it where they don’t.
Common mistakes to avoid
- One number for everything. Overspends on low-value systems and underspends on the critical ones.
- Confusing the two. Backing up more frequently when the real pain is downtime — or building fast failover when the real risk is data loss.
- Setting targets without the business. These are decisions about acceptable loss, so they need the people who own that loss, not just IT.
- Never testing. An untested RTO is a guess. The only way to know you can hit it is a real failover test.
Frequently asked questions
What’s the difference between RTO and RPO?
RTO is the maximum acceptable downtime — how long a system can be offline before the impact is unacceptable. RPO is the maximum acceptable data loss, measured in time. RTO is about speed of recovery; RPO is about how far back your last usable copy is.
Which matters more, RTO or RPO?
Neither universally — it depends on the workload. A transactional database usually needs a tight RPO; a customer-facing portal may need a tight RTO. Most mission-critical systems need both, which is why they cost the most to protect.